


Create a pipeline
- Standard pipeline: The default pipeline type that runs once per invocation to process and integrate data from start to finish.
- Resumable: Suspends instead of failing when an endpoint goes down mid-execution, allowing you to resume processing from the exact point of interruption.
- Cache: Stores up to 100,000 reference data records in memory for fast, repeated lookups within a pipeline —eliminating costly round-trips to external systems.
- MCP: Exposes SnapLogic pipelines as discoverable AI tools via the Model Context Protocol, enabling any MCP-compatible AI agent or client to invoke them seamlessly.
- Tools: Pipelines exposed as callable tools that can be invoked directly by an Agent pipeline or through an MCP Server.
-
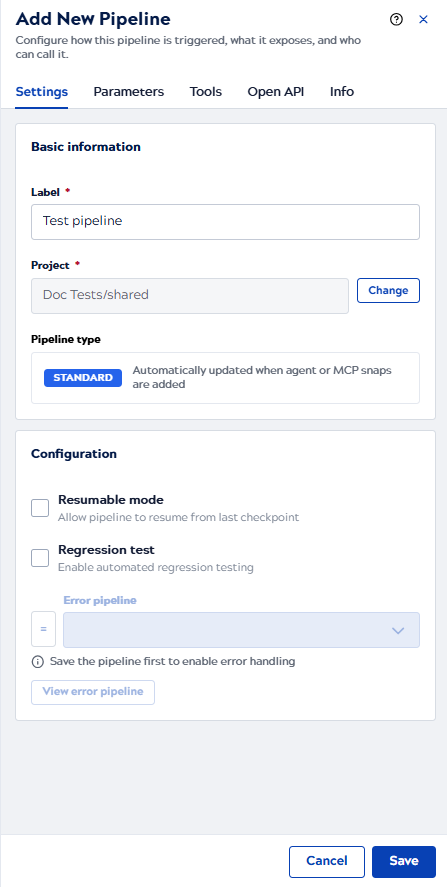
In the Designer canvas, click the Add
 icon or click the Pipeline
 icon to open
the Add New Pipeline dialog.
You can use the Snap Reference documentation to do the following:
- Determine the Snaps you need to use to build your pipeline.
- Gather account information required to connect to your endpoints.
To configure pipeline settings such as parameters, tool inputs, and expression libraries, see Pipeline properties and configuration.